Navigating Singapore’s DC Scarcity: From Crowded Colos to In-House Strains Singapore’s data centre market has never been busier — or harder to …
The CIO’s playbook for hybrid cloud amid rising AI adoption
Cloud repatriation is back on the CIO’s agenda. Forrester’s Cloud Survey found close to a third of public cloud-hosted applications are being repatriated — mostly workload by workload, not wholesale exits. IDC reports roughly 80% of enterprises expect to repatriate some compute or storage within a year, though only 8-9% plan a full exit. Gartner forecasts hybrid architectures will support mission-critical workflows at 40% of enterprises by end-2026, up from just 8% a few years ago — even as public cloud spend keeps growing past $720 billion globally.
Cost control, AI infrastructure demand, uptime, and disaster recovery are driving this shift. But here’s what most repatriation plans miss: bringing workloads home means bringing the power, cooling, and monitoring stack home too. That’s usually where the project stalls.
Get this playbook as a pdf, plus the CIO checklist
Same content, saved for later - with a one-page self-assessment checklist not published on the site.
Send me the PDFThe Part of the Plan Nobody Budgets For
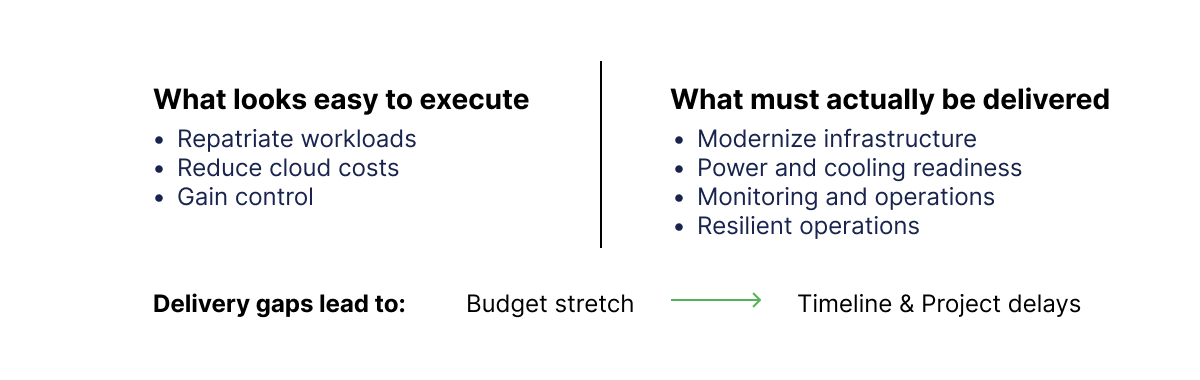
A repatriation business case is easy to build on compute alone. Move the workload, cut the cloud bill, gain control. What’s harder to model — and what derails timelines — is everything the workload depends on to actually run on-premise:
- Power: redundant, conditioned, UPS-backed power sufficient for always-on enterprise and AI workloads. AI’s appetite here is no longer trivial
- Cooling: thermal management sized for higher-density AI hardware, not legacy server rooms. Racks that used to run at 10–20kW are increasingly being pushed toward 100kW and beyond, with some analysts pointing to next-generation AI racks approaching 370kW — a jump that makes conventional air-cooled server rooms obsolete almost overnight.
- Monitoring: real-time visibility into uptime, capacity, and failure risk — the operational nervous system that cloud providers used to handle invisibly. This isn’t a nice-to-have: the Uptime Institute’s 2025 Global Data Center Survey found organisations now average 2.3 significant outages a year, and the median outage lasted 53 minutes — long enough to matter at enterprise cost-of-downtime rates.
None of this is a compute problem. It’s a critical infrastructure problem. And it’s exactly the layer that CIOs focus on.
Already spotting a gap in your own repatriation plan?
Get a free infrastructure readiness assessment before you move your workloads back.
Book my readiness assessmentThis Is Where Repatriation Projects Delay
Setting up a server is not difficult. Designing N+1 redundant power, right-sizing cooling for GPU-dense racks, and building 24/7 monitoring with recovery protocols is a different conversation — one that turns a migration project into a CAPEX-heavy infrastructure build requiring specialist know-how most enterprises don’t keep in-house. Budgets stretch, timelines slip, and the business case that looked good on a spreadsheet stalls in committee.
This is why hybrid cloud — not full repatriation — has become the pragmatic default: enterprises want the control and cost benefits of on-premise infrastructure without re-acquiring the CAPEX and specialist capabilities they spent a decade shedding.
What Happens After the Move
Getting workloads home is only half the job. Once infrastructure is back on-premise, CIOs inherit ongoing maintenance, workflow redesign, manpower for round-the-clock fault response, and a wider web of vendors to manage — the hidden second wave that CIOs need to consider.
A playbook for CIOs
-
1
Take the stress off your team's plate Power, cooling and monitoring are specialist disciplines – carrying that load in-house on top of applications and workload is how good IT teams get stretched thin. -
2
Eliminate the single point of failure A repatriation done without redundant power and proper failover design just moves the risk from a cloud region to a server room. Resiliency has to be engineered in, not assumed. -
3
Get visibility the CIO can actually rely on Real-time monitoring across on-premise and cloud means fewer surprises – and answers ready before the board asks the question. -
4
Build in resiliency from the start AI-density workloads and always-on operations leave little room for reactive fixes. Design for uptime upfront rather than patching it in after an outage -
5
Aim for operational excellence, not just uptime The goal isn’t only “nothing broke” – it’s a hybrid environment that runs predictably, scales cleanly and frees the IT/Ops lead to focus on higher-value work instead of firefighting.
Closing The Gap
For CIOs building a hybrid cloud strategy amid rising AI adoption, the real playbook isn’t cloud versus on-premise. It’s finding a partner who can deliver the full stack — compute, power, cooling, and visibility — so the capabilities gap never gets a chance to stall the project.
NaviX Solutions provides zero-CAPEX, subscription-based critical power and cooling solutions for Singapore’s enterprises and commercial building operators
Get The Full Stack - Compute, Power, Cooling and Visibility
See what a zero CapEx Enterprise DC as-a-Service model looks like for your environment
Talk to a specialist, no cost, no obligationSources
Forrester Cloud Survey (2024); IDC cloud repatriation research (2024); Gartner: Top Strategic Technology Trends for 2026; Deloitte: 2026 Hardware and Consumer Tech Industry Outlook; Uptime Institute Global Data Center Survey (2025); ITIC Hourly Cost of Downtime Survey; Splunk/Cisco “Hidden Costs of Downtime” report (2026).
You may like:
How a consumer electronics manufacturing plant optimize their server room for efficiency and growth Explore Enterprise DC as a Service You may …
Learn more:
The CIO’s playbook for hybrid cloud amid rising AI adoption
Cloud repatriation is back on the CIO’s agenda. Forrester’s Cloud Survey found close to a third of public cloud-hosted applications are being repatriated — mostly workload by workload, not wholesale exits. IDC reports roughly 80% of enterprises expect to repatriate some compute or storage within a year, though only 8-9% plan a full exit. Gartner forecasts hybrid architectures will support mission-critical workflows at 40% of enterprises by end-2026, up from just 8% a few years ago — even as public cloud spend keeps growing past $720 billion globally.
Cost control, AI infrastructure demand, uptime, and disaster recovery are driving this shift. But here’s what most repatriation plans miss: bringing workloads home means bringing the power, cooling, and monitoring stack home too. That’s usually where the project stalls.
Get this playbook as a pdf, plus the CIO checklist
Same content, saved for later - with a one-page self-assessment checklist not published on the site.
Send me the PDFThe Part of the Plan Nobody Budgets For
A repatriation business case is easy to build on compute alone. Move the workload, cut the cloud bill, gain control. What’s harder to model — and what derails timelines — is everything the workload depends on to actually run on-premise:
- Power: redundant, conditioned, UPS-backed power sufficient for always-on enterprise and AI workloads. AI’s appetite here is no longer trivial
- Cooling: thermal management sized for higher-density AI hardware, not legacy server rooms. Racks that used to run at 10–20kW are increasingly being pushed toward 100kW and beyond, with some analysts pointing to next-generation AI racks approaching 370kW — a jump that makes conventional air-cooled server rooms obsolete almost overnight.
- Monitoring: real-time visibility into uptime, capacity, and failure risk — the operational nervous system that cloud providers used to handle invisibly. This isn’t a nice-to-have: the Uptime Institute’s 2025 Global Data Center Survey found organisations now average 2.3 significant outages a year, and the median outage lasted 53 minutes — long enough to matter at enterprise cost-of-downtime rates.
None of this is a compute problem. It’s a critical infrastructure problem. And it’s exactly the layer that CIOs focus on.
Already spotting a gap in your own repatriation plan?
Get a free infrastructure readiness assessment before you move your workloads back.
Book my readiness assessmentThis Is Where Repatriation Projects Delay
Setting up a server is not difficult. Designing N+1 redundant power, right-sizing cooling for GPU-dense racks, and building 24/7 monitoring with recovery protocols is a different conversation — one that turns a migration project into a CAPEX-heavy infrastructure build requiring specialist know-how most enterprises don’t keep in-house. Budgets stretch, timelines slip, and the business case that looked good on a spreadsheet stalls in committee.
This is why hybrid cloud — not full repatriation — has become the pragmatic default: enterprises want the control and cost benefits of on-premise infrastructure without re-acquiring the CAPEX and specialist capabilities they spent a decade shedding.
What Happens After the Move
Getting workloads home is only half the job. Once infrastructure is back on-premise, CIOs inherit ongoing maintenance, workflow redesign, manpower for round-the-clock fault response, and a wider web of vendors to manage — the hidden second wave that CIOs need to consider.
A playbook for CIOs
-
1
Take the stress off your team's plate Power, cooling and monitoring are specialist disciplines – carrying that load in-house on top of applications and workload is how good IT teams get stretched thin. -
2
Eliminate the single point of failure A repatriation done without redundant power and proper failover design just moves the risk from a cloud region to a server room. Resiliency has to be engineered in, not assumed. -
3
Get visibility the CIO can actually rely on Real-time monitoring across on-premise and cloud means fewer surprises – and answers ready before the board asks the question. -
4
Build in resiliency from the start AI-density workloads and always-on operations leave little room for reactive fixes. Design for uptime upfront rather than patching it in after an outage -
5
Aim for operational excellence, not just uptime The goal isn’t only “nothing broke” – it’s a hybrid environment that runs predictably, scales cleanly and frees the IT/Ops lead to focus on higher-value work instead of firefighting.
Closing the Gap
For CIOs building a hybrid cloud strategy amid rising AI adoption, the real playbook isn’t cloud versus on-premise. It’s finding a partner who can deliver the full stack — compute, power, cooling, and visibility — so the capabilities gap never gets a chance to stall the project.
NaviX Solutions provides zero-CAPEX, subscription-based critical power and cooling solutions for Singapore’s enterprises and commercial building operators
Get The Full Stack - Compute, Power, Cooling and Visibility
See what a zero CapEx Enterprise DC as-a-Service model looks like for your environment
Talk to a specialist, no cost, no obligationSources
Forrester Cloud Survey (2024); IDC cloud repatriation research (2024); Gartner: Top Strategic Technology Trends for 2026; Deloitte: 2026 Hardware and Consumer Tech Industry Outlook; Uptime Institute Global Data Center Survey (2025); ITIC Hourly Cost of Downtime Survey; Splunk/Cisco “Hidden Costs of Downtime” report (2026).